ScaleFlux Spent 12 Years Getting Ready for the AI Memory Crunch. It Just Showed Its Hand.
At the 70th edition of The IT Press Tour in Palo Alto, ScaleFlux’s leadership laid out PCIe 6.0 SSD and CXL 3.2 silicon, its business model, and a few teasers they weren’t quite ready to explore.
Eight a.m. in Palo Alto is early for most people. Not for the ScaleFlux engineers. “Our day begins early, evenings are long, and weekends are working with each other,” Saeed Raja, VP of Memory, AI, and CXL Product Marketing & Management, told our group of ITPT journalists as the briefing kicked off. Nobody laughed harder than the people who actually live that schedule.
That detail stuck with me through the rest of the morning, because the story ScaleFlux told us is partly about timing. The company started in 2014 with a bet that was right and early at the same time. Twelve years later, the market has caught up to it.
I sat down with Hao Zhong, Co-founder and CEO, Pic Balaji, VP of Products & Marketing, and Raja. Here’s what they shared, what they announced, and why I think ScaleFlux deserves a spot on your radar.
Right Idea, Wrong Calendar
Hao’s origin story is refreshingly honest. When he and his co-founders started the company, SSDs had just crushed the old storage bottleneck, and he figured the next choke point would be the CPU. So ScaleFlux set out to offload work from the processor into the storage itself. That’s computational storage: compression, encryption, data filtering and search, all handled where the data lives.
“We were a little ahead of schedule.”
— Hao Zhong, Co-founder and CEO, ScaleFlux
The acceleration instinct was right. It just showed up first in GPUs and DPUs rather than SSDs. Meanwhile, ScaleFlux kept building. The timeline on its presentation read like a patient march: a first FPGA-based product in 2018 that went through proof of concept with one of the largest hyperscalers, the CSD 2000 series in 2020, CSD 3000 in 2022, and CSD 5000 in 2024. That last generation, Raja said, has been running at very large scale at a lead customer the company has worked with for four or five years.
Hao made a point I want to repeat, with the caveat that it’s his claim: enterprise-grade SSDs are hard enough, and ScaleFlux is the only company that has put computational storage into production at hyperscalers and enterprises. For years the market was a niche. Then memory prices went through the roof, and suddenly a drive that squeezes more data into the same flash looked a lot smarter.
The Quiet Years
If you lost track of ScaleFlux for a while, you’re not alone. The IT Press Tour founder and organizer, Philippe Nicolas, told the team they seemed to have disappeared before reappearing, with a keynote at FMS 2026 and NVIDIA on stage. Hao didn’t dodge it.
The company has about 300 people, most of its engineering leadership came from Broadcom, Samsung, and Marvell, and, according to Hao, it has raised more than $700 million. It also plans to invest $60 million-plus in India with 100-plus hires. “People always underestimate us,” he said. “We don’t make big announcements.” The quiet, in his words, was because the work “took us a lot of capital.”
Raja offered the human side of that. Companies came and went over the last 13 years, and ScaleFlux’s management team stayed put.
“There are marriages that don’t last for thirteen years, but this management team stuck together on the same core mission.”
— Saeed Raja, VP of Memory, AI, and CXL Product Marketing & Management
Three Problems, One Pipeline
Pic Balaji walked us through the industry problems ScaleFlux is built around. Think of them as three squeezes happening at once.
Squeeze One: The Most Expensive Chip in the Room Is Waiting
A GPU is the priciest component in an AI system, and nobody wants it idle. ScaleFlux’s slides showed the wait time growing with distance from the GPU. By the company’s numbers, DDR5 is roughly 37 to 40 times slower than the GPU, and a PCIe Gen 6 SSD lands around 750 to 800 times slower. If the pipeline is too narrow, the data doesn’t show up when the GPU needs it. Simple as that.
ScaleFlux frames the fix as a set of tiers, and Hao rattled them off during the opening remarks:
- G1/G2: system memory
- G2.5: CXL-attached memory
- G3: local SSD
- G3.5: context storage for KV cache workloads
- G4: network storage
Every one of those tiers needs a controller to manage data movement, and that controller is where ScaleFlux lives.
Squeeze Two: There Isn’t Enough to Go Around
Pic’s second chart was the one that made the room take notice. For 2027, ScaleFlux estimates demand from roughly 9 to 10 million GPUs, 20 to 25 million enterprise servers, and 55 to 60 million enterprise SSDs. That works out to about 3 exabytes of HBM, 20 to 30 exabytes of DRAM, and 500 to 600 exabytes of enterprise NAND.
Put that in terms of share and the picture gets lopsided. HBM covers less than 1% of memory need, DDR5 about 5%, and NAND the other 94% or so. Pic’s read: last year everybody was talking about CPUs and GPUs, this year everybody woke up and started talking about memory, and “storage is still at the tip of the iceberg.”
Squeeze Three: One Size Fits Nobody
You’d think “AI storage” is one thing. It isn’t. AI training cares about fast checkpointing. Inference cares about IOPS and low latency for KV cache. Hyperscalers care about fleet-wide consistency, so a server in the U.S. behaves the same as one in Europe or Australia. Enterprise customers want predictable performance and no annual drive swaps. Neoclouds, Pic said, “want everything” and care most about throughput per GPU.
Then there’s the corner of the market Pic called the least valued: enterprise boot. A lot of people, he said, still believe they can take a client controller and turn it into an enterprise boot device. Raja, who came up through Micron and Marvell, was blunt: “We learned these things the hard way. It doesn’t work.” Data center boot SSDs have their own security and latency demands.
“Move Data, or Don’t?” Yes.
One of the sharper questions during the session pointed at ScaleFlux’s own vision statement. The company says it wants to be “the silicon foundation that moves AI data at the speed of compute.” But isn’t the whole industry saying stop moving data and compute where it lives?
Hao’s answer cleared up an apparent contradiction nicely. It’s not either/or. Moving data costs power and creates bottlenecks, so you avoid moving it until you have to. But some work, such as compression, data prep, and vector operations, should happen in the storage or memory layer, and when data does have to travel, the path needs to be fast.
“It should happen at the right place at the right time.”
— Hao Zhong, on where acceleration belongs in the data pipeline
That philosophy explains why ScaleFlux has grown from a computational storage drive company into something broader. It’s also working with NVIDIA and memory partners on “Storage-Next” style efforts, trying to push IOPS up by as much as ten times.
What Actually Landed: FC6116 and MC600
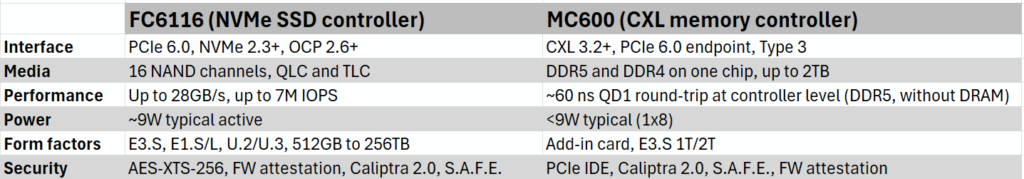
At FMS 2026, ScaleFlux announced two flagship chips, and both were on display just outside the briefing room. As Raja noted, “those are not empty shelves.” Both are sampling.
FC6116: The SSD Side
The FC6116 sits on top of the FC5116, a PCIe 5.0 controller that, Pic said, has been in production for more than a year and a half. He called the Gen 6 part ready to sample, with general availability targeted for around the middle of next year. That timing, he added, depends heavily on when customers finish qualifying it for their own fleets, and ScaleFlux could go sooner.
Two features stood out. First, the controller supports 200-plus FDP (Flexible Data Placement) streams per SSD, which ScaleFlux developed with a major AI GPU company to serve KV cache. Second, the company says that using only its controller capabilities, with no changes to standard TLC NAND, it can stretch endurance to 7 to 10-plus drive writes per day. That’s a big claim, and I’d like to see it in customer deployments, but it’s the sort of trick that helps when inference workloads hammer flash with small writes.
Pic also stressed the multi-NAND angle. ScaleFlux supports all the major NAND vendors, up to 4800 MT/s, and both QLC and TLC. His pitch: ScaleFlux is the only United States SSD controller company with full-stack firmware for an enterprise-class product that can work across multiple NAND suppliers. Hao added respect for the incumbents, naming Broadcom, Microchip, and Marvell, but argued they’ve historically struggled to hand customers a turnkey firmware solution, something that can take a customer two years to develop on their own.
MC600: The Memory Side
Raja owns the CXL story, and he joined ScaleFlux about four and a half years ago because he was inspired by what CXL could do. The MC600 follows the MC500 (CXL 3.1, PCIe 5.0), which went through extensive hyperscaler testing. ScaleFlux has a working add-in card and E3.S module, plus a validated reference architecture using DRAM from all three major memory suppliers.
What sets it apart, according to Raja, is a short list of things hyperscalers lose sleep over: low latency, low power, and server-grade RAS (reliability, availability, serviceability) that tolerates heavy DRAM hard and soft failures. He explained why that last one matters so much. If a CXL controller takes down a fleet, the first phone call goes to Intel or AMD, not ScaleFlux. So the company developed its approach in collaboration with NVIDIA, hyperscalers, and memory partners, and published white papers on the work.
Security is the other piece. Raja said part of why CXL adoption has dragged was the lack of security features, and ScaleFlux built secure boot with a hardware root of trust, firmware attestation, and IDE link encryption.
The Part They Wouldn’t Fully Explain
Every good briefing has a moment where the executives look at each other and decide how much to say. This one had a few.
The headline tease was transparent compression for DRAM. ScaleFlux has years of compression experience in SSDs, but Raja said the market wasn’t ready for it in memory until recently. The idea is capacity multiplication: physical DRAM stays fixed, CXL expansion and tiering add to it, and compression stretches what’s usable, so you get more memory per dollar. Before Raja went too far down the roadmap path of what their next chip “may” include, Hao pumped the brakes, saying it’s too early to discuss and “we should talk about that more next year.” Raja had a counteroffer: come back for a closed-door session on the next tour.
When pressed on the “black box” worry, Raja was firm: “It’s not a black box. It has to be transparent.” And since nobody is supposed to peek at what runs inside a customer’s VM, he said the approach relies on data patterns and metadata, not content.
The second tease was CXL meets NAND. Today CXL controllers mostly handle DRAM expansion, Hao clarified, but ScaleFlux’s SSD controllers also have CXL features. Raja put it like this: ScaleFlux has a very reliable CXL controller and a very reliable NAND controller, “what stops us from putting them on the same package?” Hao said pilots are underway with early partners, though productization is at an early stage. Raja hinted at a public proof of concept in the near future, plus possible production news around GTC. So, we’ll stay tuned.
The Real Story: A Chip Company That Won’t Compete With Its Customers
If the silicon is the headline, the business model is the plot twist. Pic described a wish: SSDs built like Lego blocks, with a full recipe attached, that you can assemble to fit an application and manufacture at volume. ScaleFlux has turned that wish into four engagement models:
- Custom: a differentiated SoC for customers who want to build their own CXL and SSD products with their logo on the chip.
- Merchant: standard ScaleFlux roadmap parts with full turnkey firmware.
- Solution: reference designs and boards that contract manufacturers or hyperscalers can build from.
- Module: ScaleFlux-branded SSD modules for those who want plug-and-play.
Asked for a revenue split, Hao gave a rough idea with a warning that one hyperscaler order can “flip the table.” For this year, he put custom ASIC at about 20%, merchant devices around 30%, and solution plus module around 50%.
Here’s the twist that I think matters most. Even for module sales, ScaleFlux doesn’t book the SSD revenue. It passes that to partners. Hao used a comparison I liked: Intel and AMD can build servers, but they leave that to Supermicro, Quanta, and Foxconn, because those companies are better at supply chain operations.
“We want to be a fabulous solution company, not just a chip company. It’s actually a chip plus solution company.”
— Hao Zhong
An SSD, Hao pointed out, is essentially a small server: a controller, DRAM buffer, NAND, power ICs, and a PCB. Companies like Kingston and Quanta already run massive operations around inventory, sourcing, and orders. ScaleFlux would rather make those companies better than replace them. It took him almost a decade, he said, to land on that model.
Who’s Buying, and Why
Hao described three kinds of customers, and the logic is tied directly to the supply crunch:
- Hyperscalers typically hold their own long-term supply agreements for NAND and DRAM.
- Memory companies that want custom or alternative solutions.
- Contract manufacturers and module houses that have secured memory supply but lack the controller and firmware expertise. They use ScaleFlux silicon and firmware, then ship to server OEMs, neoclouds, and enterprises.
The partner program already includes names like Unigen, plus VAST Data, which Hao described as a system company that used to buy standard SSDs. Then supply got tight, and VAST wanted features a stock SSD couldn’t offer. ScaleFlux customized the firmware and introduced contract manufacturers to build to VAST’s spec. Hao called the current list “just the first few that signed up.”
They Say No, Too
I appreciated the honesty on volume. ScaleFlux won’t chase every deal. Hao laid out rough thresholds:
- A few hundred to a few thousand drives: ScaleFlux points you to a module-house partner.
- Customer-specific firmware: expect hundreds of thousands of units.
- A custom ASIC: a commitment north of $10 million.
Raja was equally direct: “We have said no to multiple products.” The company wants to make a profit, but not at the customer’s expense.
Why You Should Pay Attention
So where does that leave us? ScaleFlux is a company that spent twelve years building the unglamorous parts: in-house controller IP, NAND PHY, ECC, turnkey firmware, a pool of manufacturing partners, and the relationships to tie them together. Most of that took years to assemble. You can’t buy it overnight, and in a market where Pic says everyone can “work really hard and still not find enough SSDs,” it matters.
Add the timing. PCIe 6.0 and CXL 3.2 silicon are sampling now. Memory is the topic of the year. Enterprise boot, KV cache, and fleet-wide efficiency all need purpose-built answers rather than one-size-fits-all SSDs.
To be fair, a few things remain to be proven. The DRAM compression story is a teaser, not a product. CXL-attached NAND is early. The 10 DWPD claim needs real-world evidence, and customers are mostly anonymous. But ScaleFlux’s leadership seemed comfortable with that. They aren’t asking for blind trust; they’re showing working hardware and telling you when to come back.
Here’s what I’ll be watching:
- General availability of the FC6116, targeted for around mid-2027.
- Production news from ScaleFlux’s CXL work, possibly around GTC.
- A public proof of concept for CXL with NAND.
- The closed-door briefing on DRAM compression, if we get that invitation next year.
Hao summed up the company’s position at the close: ScaleFlux started in computational storage, but it’s now “a silicon platform company,” agnostic to memory and compute platform alike. After a decade of being early, that’s a pretty good place to be on time.
##